expertdial
Spike: steering MoE LLMs by banning/forcing experts in llama.cpp
- Stars
- 1
- Language
- Python
- Updated
expertdial — see and steer the experts inside a MoE model
A local tool for watching a Mixture-of-Experts model route each token, and changing that routing while it answers. Every expert is a cell in a grid: it lights up when the token goes through it, and clicking it bans that expert or forces it on. The model picks up the change on the very next token.
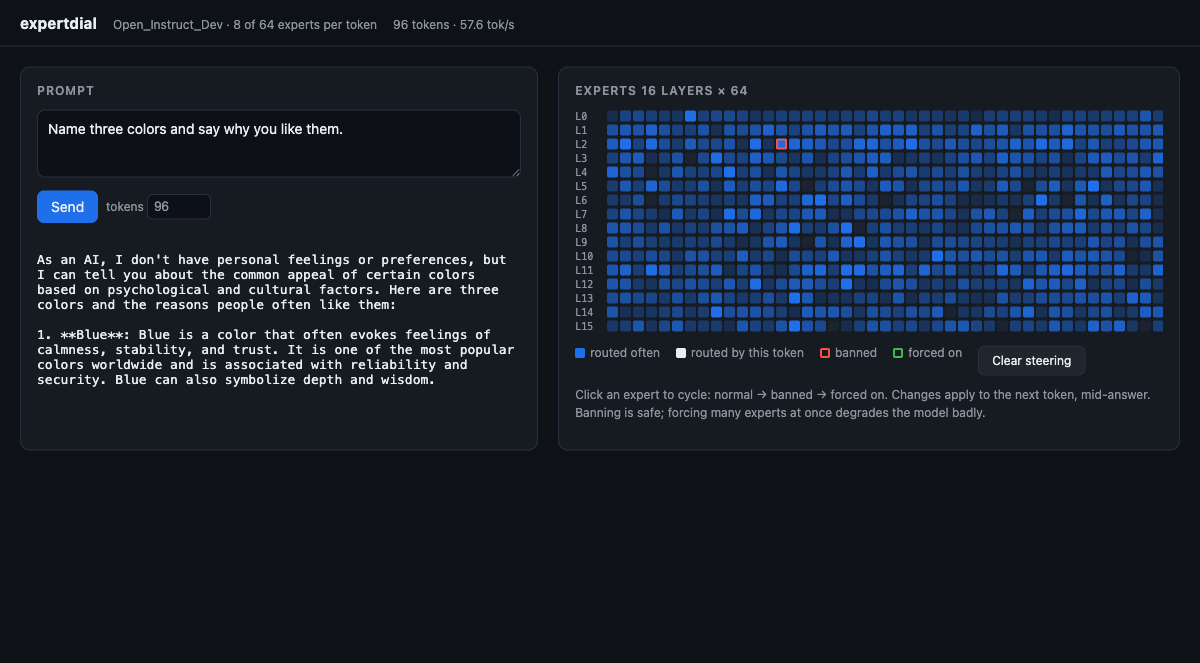
Built on a small patch to llama.cpp, so it runs any MoE model in GGUF format (OLMoE, gpt-oss, Qwen3, DeepSeek) on a laptop.
app/run.sh models/OLMoE-1B-7B-0125-Instruct-Q4_K_M.gguf     # then open http://127.0.0.1:8777
app/run.sh models/gpt-oss-20b-MXFP4.gguf 0                  # 0 = CPU only, for models too big for your GPU
Verified live on gpt-oss-20B: an expert used by 4 of 12 tokens dropped to 0 of 12 the moment it was banned, and the wording of the answer changed with it.
What it is for: seeing which experts fire, and running your own routing experiments. What it is not: a reliable behaviour dial. We tested that claim carefully and it did not hold up — see the findings below, which are as much a part of this repo as the tool.
Findings
Before building the tool we asked: can we steer a Mixture-of-Experts model's behaviour at inference time by banning or forcing experts in llama.cpp? If so, it's worth building a live "click an expert to steer" tool.
Pass bar, agreed before running:: at least 2 of 3 visibly controllable.
- output language,
- following the provided document (faithfulness),
- with output that stays coherent.
Models: OLMoE-1B-7B-0125-Instruct (Q4_K_M) and gpt-oss-20B (MXFP4), on an Apple M2 Pro, 16GB. gpt-oss ran CPU-only at about 16 tok/s, because 12GB of weights plus Metal buffers don't fit in 16GB of shared memory.
What's here
patches/llama.cpp-moe-steer-spike.patch— applies to llama.cpp (base commit inpatches/BASE)src/llama-graph.cpp(build_moe_ffn): readsLLAMA_EXPERT_BIAS_FILE(lines oflayer expert sign).sign > 0forces the expert to the max router logit + 0.01 (SteerMoE-style "activate");sign < 0bans it.tools/moe-spike:llama-moe-spikerecords per-layer expert selection counts (MOE_MODE=trace) and generates greedily (MOE_MODE=gen).
app/: the viewer —serve.py(drives the engine, serves the UI),index.html,run.shtools/moe-spikealso hasMOE_MODE=serve: JSON lines in, per-token routing out
spike.py: prompt sets, contrastive expert discovery, scorers (including gpt-oss final-channel extraction)run.sh,sweep.sh,gptoss.sh: experimentsadobe_ranking.py: converts SteerMoE's released expert rankings into steering filesdata/: prompt sets;work/: routing traces, generations, steering files
Results
The mechanism works exactly as intended
Banned expert: 0 selections out of 440 tokens. Forced expert: 440 of 440. Still 8 experts per token. The llama.cpp patch is sound; what follows is about whether steering controls behaviour.
Language control: fails
Steering toward French on OLMoE. French only appears once the model is already breaking down. Perplexity is measured on 60KB of Pride and Prejudice; baseline 12.27.
| Setting | French / 15 | Perplexity | Sample |
|---|---|---|---|
| none | 0 | 12.27 | fluent English |
| boost k=5, +2 | 1 | 13.16 | fluent English |
| boost k=10, +2 | 4 | 42.6 | "Un weekend ideal in formeu súll o…" |
| boost k=10, +3 | 7 | 2083 | garbage |
| boost k=20 / ban k=20, ±4 | 0 | 73,676 | garbage |
The French-vs-English experts are real (the top one fires on 92% more French tokens), but pushing them doesn't produce French.
Faithfulness: changes answers, no reliable direction
40 counterfactual documents ("the capital of France is Lyon"), scored on whether the answer follows the document. Steering uses Adobe's own released rankings, so this isn't a flaw in our expert discovery.
| Model | Setting | Follows document | Flips (toward / away) | McNemar p |
|---|---|---|---|---|
| OLMoE | none | 22/40 | — | — |
| OLMoE | Adobe "faithful" (ban 50) | 27/40 | +8 / −3 | 0.23 |
| OLMoE | opposite direction | 24/40 | +8 / −6 | 0.79 |
| gpt-oss-20B | none | 24/40 | — | — |
| gpt-oss-20B | Adobe "faithful" (force 10, ban 50) | 27/40 | +9 / −6 | 0.61 |
Steering changes a lot of individual answers (15 of 40 on gpt-oss) but the direction is indistinguishable from noise at n=40. Notably, the "opposite" steering also scored slightly above baseline.
Coherence: survives bans, dies under boosts
Bans barely move perplexity (OLMoE 12.27 → 12.35). Boosting is what destroys the model.
One unexplained result: on gpt-oss, Adobe's faithful set lowered perplexity from 243.6 to 154.4 on English prose. A steering set that removes 50 experts shouldn't improve language modelling; this needs explanation before anyone trusts these numbers.
Two tests hit ceilings and couldn't measure anything
- With an explicit "use only the document" instruction, OLMoE already scores 38/40, leaving no room to improve.
- gpt-oss refuses all 20 plain AdvBench requests, steered or not (20/20 both ways). The paper's safety gains are measured on harder jailbreak sets we did not attempt.
Verdict
Fails the pass bar: 1 of 3. Coherence holds under bans; language control doesn't exist without breaking the model; faithfulness moves answers but not reliably in either direction. On this evidence, "click an expert to steer your model" is not a product yet.
What this does not rule out:
- Larger models (the paper's headline numbers come from Qwen3-30B and gpt-oss-120B).
- The paper's actual benchmarks (FaithEval, jailbreak suites) rather than our 40 hand-written items.
- Quantisation: Adobe's rankings were computed at bf16 in vLLM; we ran Q4_K_M and MXFP4.
- Safety steering, which we could not measure because refusal was already at 100%.
Anyone continuing should first run a benchmark whose baseline sits near 50%, with n in the hundreds, before trusting any steering claim.
Reproduce
cd llama.cpp && git checkout $(cut -d' ' -f3 ../patches/BASE) && git apply ../patches/llama.cpp-moe-steer-spike.patch
cmake -B build -DGGML_METAL=ON && cmake --build build -j --target llama-moe-spike llama-perplexity
cp build/bin/* ../bin/
# fetch models into models/ and 60KB of text into data/ppl.txt, then:
python3 spike.py make && ./run.sh trace && ./run.sh bias && ./sweep.sh   # OLMoE
python3 adobe_ranking.py && NGL=0 ./gptoss.sh                            # gpt-oss-20B